
Evaluators
Generated evaluations preserve provider finish reasons. A response stopped by its output token limit remains inspectable, but the sample is marked degraded and its judgments are skipped rather than assigned quality zeros. Degraded samples are excluded from trusted score aggregates and counted in run health. Check this coverage before comparing model quality: a high average over the few complete samples is not a successful overall run. Training-linked evaluations with degraded evidence report failure and no headline comparison score. Rubric judges default to generative grading. Qualified bounded checklist, claim-support and per-turn decisions can opt into Jev with generative fallback. Authoring and holistic reasoning remain generative. Evaluator policies and score provenance identify which path ran. An evaluator is one reusable, versioned scorer — editing one writes a newversion row, so past runs keep meaning what they meant. Five kinds exist:
- LLM judge (llm_judge)
- Deterministic (deterministic)
- Trajectory (trajectory)
- Agentic (agentic)
- Statistical (statistical)
A model grades the response against a rubric you write in plain language. The rubric is compiled into a checklist of atomic, weighted yes/no questions; on a boolean evaluator an item can be a gate that fails the verdict regardless of the rest. Judges return reasoning and per-item sub-scores. The managed Correctness and Faithfulness judges use a proportional mode instead: they enumerate the output’s claims and score the share that holds. Judge responses are cached content-addressed, so re-scoring identical inputs is free.
final_output, turn, step, trajectory, sample, or dataset), a score type (numeric, categorical, or boolean) with a pass_threshold, an evidence requirement (model_output, harness_artifact, trajectory, or reference), and a surface — model, harness, or any — that says where it may run: a model grader never runs on live trace scoring, a harness grader never runs on a generate variant. If a run cannot supply the required evidence, the evaluator abstains or is marked not-applicable instead of producing a number.
Claims
Every evaluator also carries a claim: what it asserts and at which grain. The claim is what trace scoring uses to compose one execution score out of many verdicts.
The grain is the slice a claim is judged on:
unit (one turn or step), trajectory (the path through the behaviour), terminal (the deliverable), or session (the whole conversation). Grains land in three weighted phases — steps, trajectory, output — and no single evaluator vetoes the composite.
Behaviour bindings
An evaluator can be bound to one of the capability’s behaviours with a role: an outcome evaluator judges the behaviour’s deliverable, a step evaluator judges one anchor segment of its route. The Eval library groups evaluators by behaviour (the Console labels it “Task”), shows each behaviour’s coverage (outcome plus every step), and lists the rest under Unassigned.GET /api/behaviours/coverage/?capability={id} returns the same rollup.
Judges are authored behaviour-scoped from the behaviour’s group in the Eval library or through the upsert_evaluator MCP tool: POST /api/evaluators/author/ takes behaviour, behaviour_role (outcome or step), and — for a step judge — the anchor_segment, validated against the behaviour’s contract. GET /api/behaviours/{id}/authoring-context/ grounds the authoring with the behaviour’s latest contract: anchor sequence, steps, tool set, and terminal. A judge whose applicable_roles include trace_scoring must be bound to a behaviour, and eval_set plus eval_set_role attach the new judge to an eval set in the same call. PUT /api/evaluators/{id}/author/ re-authors an existing judge.
Authoring
Author from the Eval library by hand, or describe what you want to test and let Overmind generate the evaluator (POST /api/evaluators/generate-prompt/). The generated prompt template references the agent’s output as {{output.<path>}} and dataset fields as {{reference.<path>}}, and everything stays editable before saving.
overmind sync refreshes the Default eval set of every current capability, in tiers: Tier 0, rule-based checks compiled from the capability’s card (its output contract, fields, and constraints — no model call); Tier 1, generative LLM judges grounded in the card, the prompt, and the behaviour map; and the behaviour outcome and step judges for trace scoring. Tier 1 authors once per capability; when it authors nothing for the generative role, one floor judge fills the role until a later push covers it. Authoring reads the capability’s evidence profile — what its telemetry carries (declared behaviours, explicit units, real tool spans, provenance tags, a declared deliverable) — and refuses a spec whose evidence the traces cannot supply.
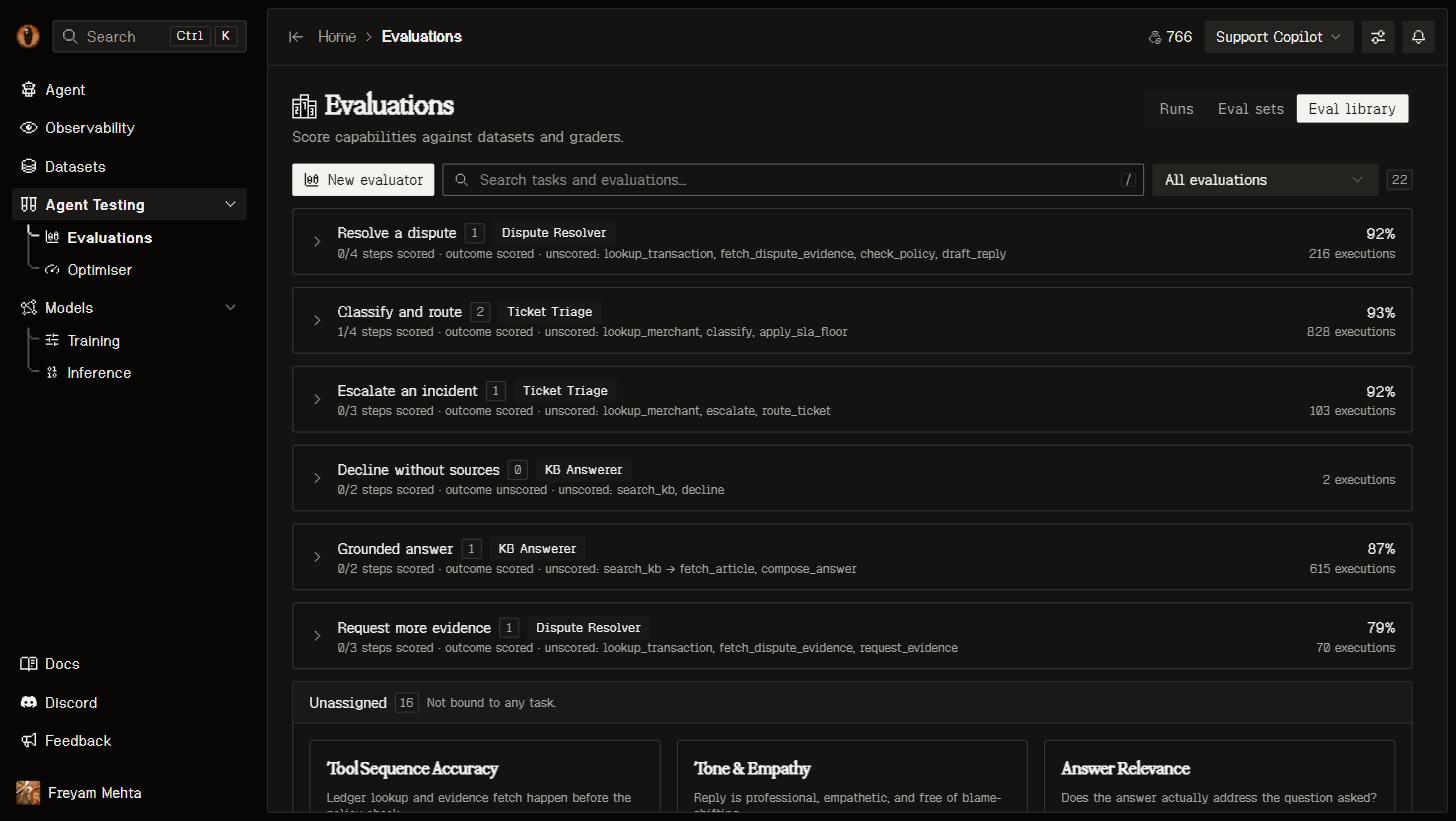
The Eval library grouped by behaviour, with each behaviour's outcome and step coverage.
Eval sets
An eval set is a named group of evaluators, optionally mapped to a capability. On Evaluations → Eval sets, choose New eval set, enter a name, and search the whole evaluator library by name, type, or mapped capability. Select multiple evaluators; selected rows show their name, type, and capability and can be removed before creation. Leave capability set to None for a reusable project set.POST /api/eval-sets/ accepts evaluator_ids and an optional nullable capability;
the set and members are created together. MCP provides create_eval_set and the
read-only overmind://eval-sets/{eval_set} resource. Neither creation path starts
an evaluation or activates the set. Each member receives its applicable roles:
generativemembers score outputs produced during eval runs and optimisation runs.trace_scoringmembers run on every production trace, per task execution, writing verdicts and the execution score into Observability. The mechanics are on Trace scoring.
POST /api/eval-sets/{id}/activate/); it is what trace scoring, optimisation runs and training runs default to. POST /api/eval-sets/{id}/members/ adds members.
A set without a capability can be selected for project evaluation and training,
but cannot be activated for live trace scoring until a capability is assigned.
Eval runs
Context warnings
Training setup shows advisory context estimates for the model being evaluated and its generative judges. These include prompt, tools and reserved output tokens. Judge preflight uses reference-answer size as a proxy for the answer that has not been generated yet. Unknown model limits are shown as unverified. These are estimates, not exact tokenizer counts; warnings never prevent launch. The Judge model selector below Eval set starts with the set’s saved judge or Mixed models when its evaluators use different judges. A selection applies to this training run’s generative judges and fallbacks, not the saved set or its Jev policy. The dropdown marks estimated context fit and shows the budget change across all judges for one dataset pass per evaluated model. Undersized options are greyed out but remain selectable. Estimated limit overflows turn the affected judge or benchmark selector orange. Start also turns orange with a warning icon; clicking it opens a short risk summary with Start anyway. Unverified, unavailable and pending checks stay neutral and do not open this warning. Changing the model is optional. Before launch, context warnings suggest alternatives with verified context and output capacity. Judge suggestions preserve configured model order, exclude the model family under test and require structured-output support. Generation suggestions require tool support when the input declares tools. These checks do not predict model quality. No suggestion changes the selection automatically. A judge change should be applied to both sides of a comparison. Evaluation cost comparisons use published token rates, all checked rows and the full reserved output for one pass per model or judge. They are not a total-run quote: retries, extra tool turns, caching, hosting and training are excluded. Missing prices remain unavailable. In training setup, training alternatives use the existing dataset ranking and show training-cost and duration estimates for their recommended configurations separately from judge evaluation costs. Benchmark deployment costs are not inferred from the base model’s token prices. API clients can preview a selected version withPOST /api/eval-runs/context-check/
using project, dataset, optional cell, eval_set, capability, variants
and a run-specific judge_model. The response includes judge_models with fit
and budget comparisons. Training launch accepts the selected eval_judge_model;
omitting it preserves the eval set’s per-evaluator models.
Each preview variant can supply output_tokens for a planned absolute output
reservation; otherwise the registered model parameters or provider-call default apply.
The request reads data without launching a run or calling a model. MCP
check_evaluation_readiness accepts proposed variants and judge_model and returns
advisory context_checks and judge_models; these do not change ready.
MCP start_finetune accepts eval_judge_model. Standalone REST creation and MCP
run_evaluation accept judge_model, matching the preview. Omit it or pass blank
to preserve each evaluator’s saved judge. An explicit choice applies only to that
run’s generative judges and fallbacks, including replay judges attached after launch;
it does not edit the library, deterministic checks or Jev policy. Judge selection
is frozen once created: start a new run to use another judge. Run detail shows the
snapshot judges; the MCP run resource exposes judge_model, run_evaluators and
the context checks.
Runtime checks use the actual model messages and assembled judge prompt. The judge
funnel preserves that prompt instead of clipping it to a fixed character limit.
If a judge exhausts its output budget, it can retry once with a larger budget only
when published context and output limits permit it. It does not switch judges or
shorten the evidence. Permanent context rejection and exhausted grading attempts
are technical errors, not quality zeros. Score _judge metadata records attempt
budgets, finish reasons, usage, request IDs and costs where the provider supplies them.
Configuration
An eval run is one experiment: one data source × N variants × M evaluators.- Data source —
dataset(the version is used and frozen, so the run stays reproducible as the dataset evolves) ortrace_filter, drawing directly from captured traffic.max_itemscaps how many rows are drawn. - Variants — the columns of the experiment. A variant’s
modeisgenerate(re-run a model over each row) orexisting(grade the recorded output as-is). Each pins a model (a catalogue model, a registered endpoint, or one of your trained models) and optionally a prompt; one variant is the baseline (is_baseline) every other is measured against. - Evaluators — attached as frozen snapshots at creation, so later library edits cannot change what a completed run measured.
run_evaluation MCP tool. An eval dataset’s cell also offers Run the optimiser and Use in a training job.
status moves pending → running → completed, or ends failed or cancelled.
For recorded conversations, a generated variant can set params.generation_strategy to per_assistant_turn. The model produces one decision for each recorded assistant turn, using the conversation recorded before that turn as context. Tool calls are evaluated as decisions without executing their tools. Each subsequent turn uses the recorded history, keeping its context independent of the candidate’s previous decisions. Such a run attaches a per-turn judge automatically, and params.replay_dimensions names what it grades. This also applies to conversations containing a single recorded assistant turn; a tool-only decision does not require a final answer.
A sample that exceeds the generation worker’s time limit records an error and is excluded from scoring. Scoring starts after sample preparation finishes, so a run can be generating while its score count is still zero.
Reading the report
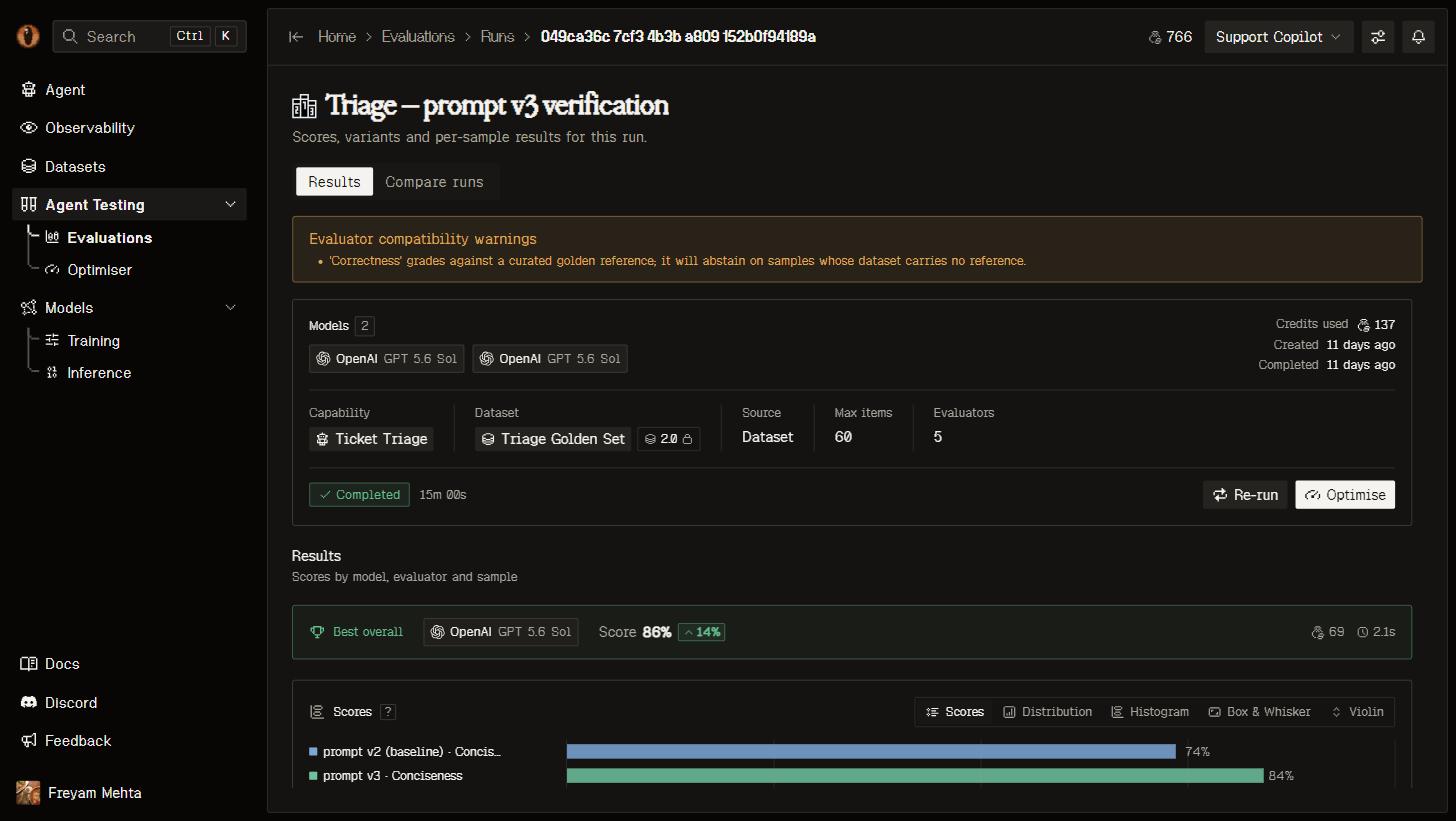
A finished run: per-evaluator pass rates and mean scores per variant, the score distributions, and cost and latency per model.
overmind://eval-runs/{eval_run} resource exposes up to five bounded sample inspections with separate input, output, reference, and evaluator reasoning. input_source distinguishes captured requests, pinned dataset rows, and unavailable input; samples_truncated indicates additional samples.
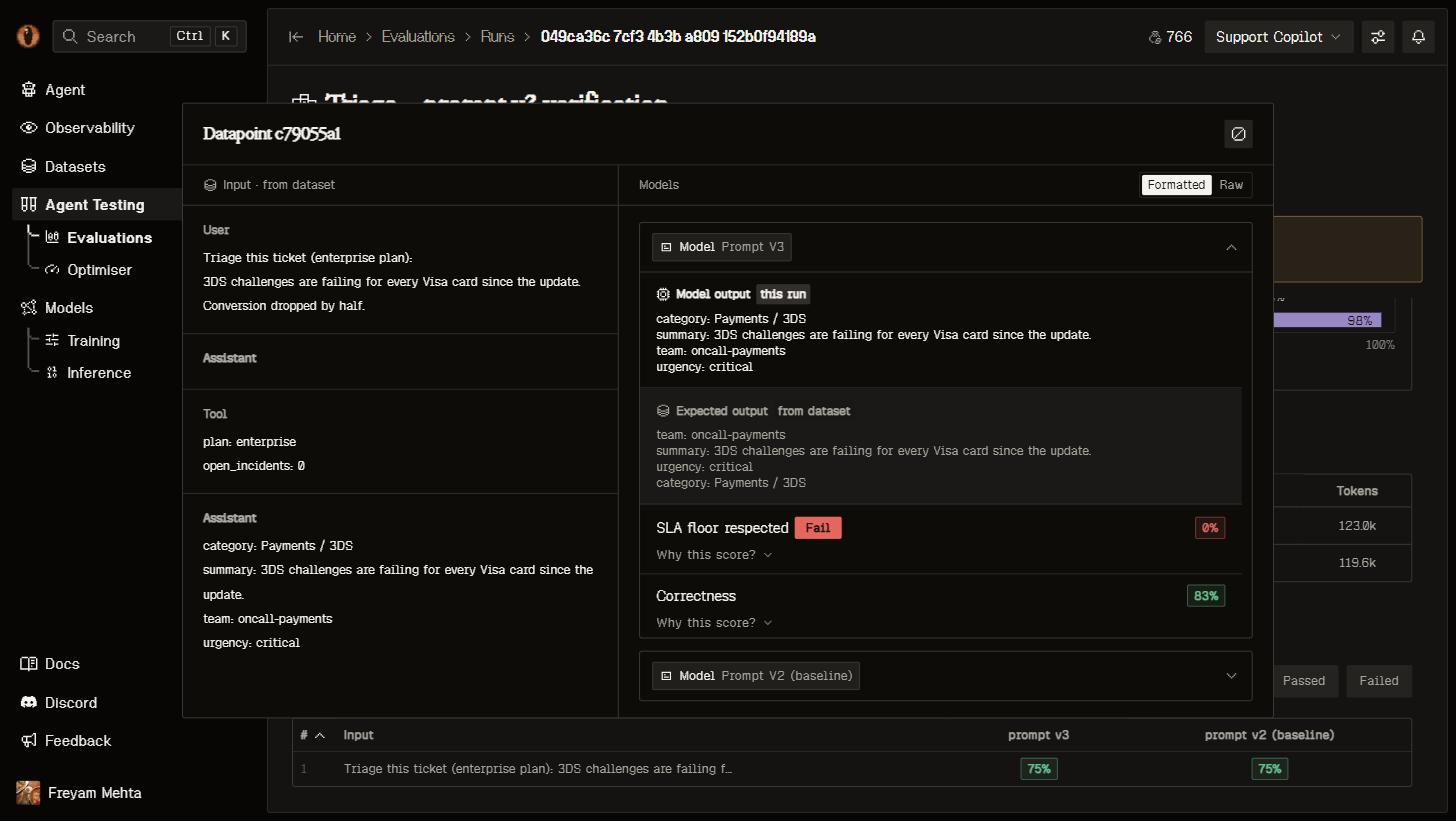
Datapoint drill-down: each evaluator's score with reasoning. A check that could not be applied is not-applicable and does not enter the averages.
- Outcomes are typed. Every score’s
outcomeisscored,abstained,not_applicable,skipped, orerror— and onlyscoredresults feed averages and pass rates. - Samples can be degraded. Each trace is normalised into a canonical transcript before scoring; if it cannot be reconstructed, the sample is marked
degradedwith adegraded_reasonand excluded from aggregates. Failure scores also carry afailure_role—root_causeorpropagated— so one upstream failure does not read as five independent ones.
GET /api/evaluators/score-history/) that powers the trend chart on the capability page.
Calibrating judges
Samples accept annotations — human labels with an optional note, written through theannotate_evaluation_sample MCP tool — giving you ground truth to compare judge behaviour against. When a judge and your annotations disagree consistently, tighten the rubric; the compiled checklist shows which criterion is drifting.